S13 Bonus: The Enterprise AI Chip War: Rethinking LLM Silicon & Inference with Vasanth Mohan, Director of Product at SambaNova
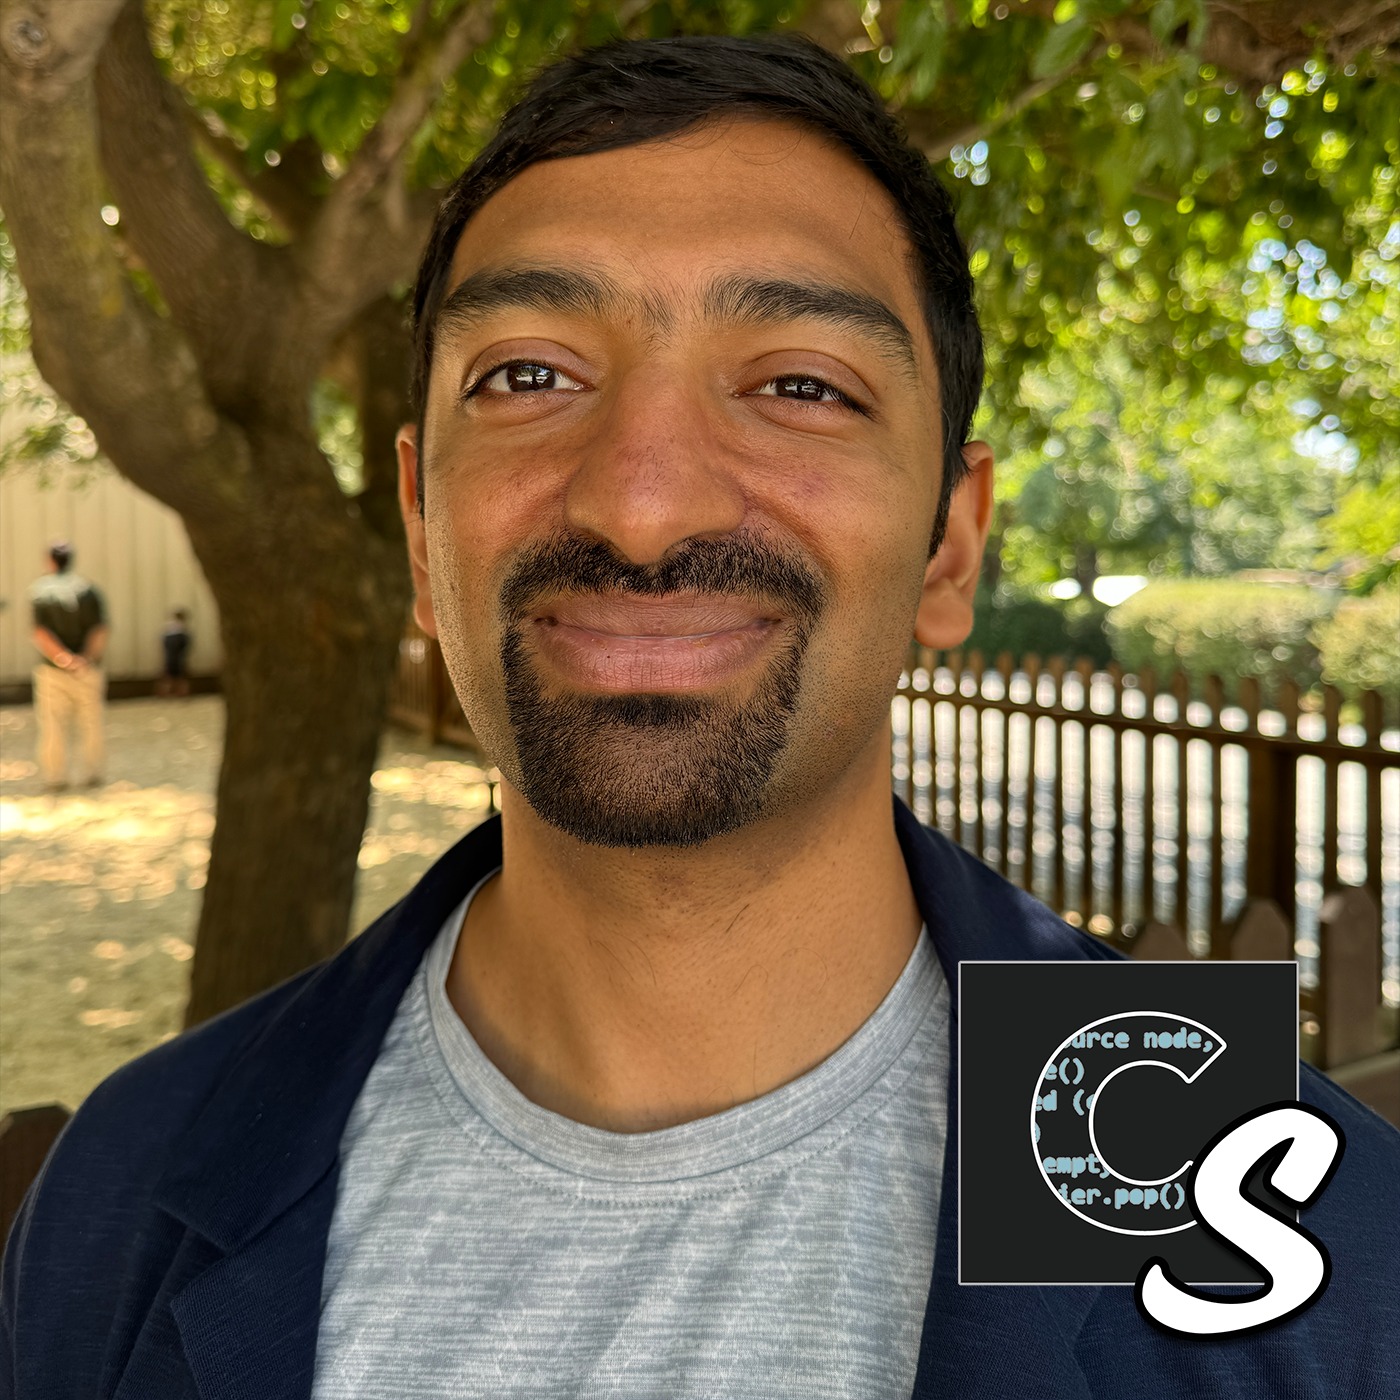
Today, we welcome a special guest to the podcast, Vasanth Mohan, Head of Developer Relations and Product Marking at SambaNova.
SambaNova is transforming AI with efficiency, security and sovereignty, driven by their relentless pursuit of intelligence, and running the largest models by maximizing dataflow efficiency. Vasanth and I dig into some fun - and heavy - topics at the backbone of where the industry is going with AI Inference, specifically at the hardware layer.
Questions:
- Tell me and the audience a bit about you and SambaNova.
- The Shift to Autonomy: "When we shift from a user generating a single chat response to an autonomous coding agent executing dozens of background tool calls, loop checks, and file rewrites, how does the underlying inference profile change, and what metric breaks first?
- Latency Budgets: "Token-per-second throughput used to be a nice-to-have metric for human readability, but for multi-agent workflows running in parallel, low latency is critical to prevent system timeouts. How are developers designing prompt structures and context windows to prevent compounding latencies during multi-agent orchestration?
- Hardware Heterogeneity: "Hyperscalers historically standardized on monolithic hardware, but neoclouds are increasingly mixing high-memory GPUs, specialized inference ASICs, and custom interconnects. How do you decide the optimal hardware mix inside a rack when your customer demand fluctuates between massive long-context reasoning models and rapid edge-like decoding?
- Power and Rack Density: "With high-end inference accelerators drawing massive power per node, how are neocloud data centers re-engineering liquid cooling, rack layouts, and power distribution specifically to maximize inference density rather than training throughput?
- Decoupling Prefill and Decode: "Disaggregated inference splits compute-heavy prefill operations from memory-bandwidth-heavy decode operations onto distinct hardware pools. What are the biggest real-world friction points when deploying this in production—especially around KV-cache transfer overhead and inter-node networking?
- Dynamic Orchestration: "In a disaggregated setup, workload spikes in long-context coding prompts can saturate the prefill pool while leaving decode nodes underutilized. How are leading engineering teams building smart routing layers and dynamic auto-scaling engines to balance compute across compute-bound and memory-bound hardware?
- The Economic Tipping Point: "Enterprise adoption is oscillating between proprietary API-driven models and self-hosted open-weights models. At what scale—measured in inference volume, latency SLAs, or data privacy constraints—does it become economically imperative for a company to transition off closed APIs onto self-hosted open infrastructure?
Links
https://www.linkedin.com/in/v-mohan/
Current Sponsors:
Checkout our Stacklist! https://stacks.codestory.co/
Hosted by Noah Labhart | Technical Founder & Startup Mentor.
Advertising Inquiries: https://redcircle.com/brands
Privacy & Opt-Out: https://redcircle.com/privacy
[SPEAKER_01]: Hello listeners, today we welcome a special guest to the podcast, the Sonthe Mohan, head of developer relations and product marketing at Samba Nova. [SPEAKER_01]: Samba Nova is transforming AI with efficiency, security, and sovereignty driven by their relentless pursuit of intelligence, and running the largest models by maximizing data flow efficiency. [SPEAKER_01]: The Sonthe and I dig into some fun and heavy topics at the backbone of where the industry is going with AI inference, specifically at the hardware layer.
[SPEAKER_01]: So thank you for being on the show today. [SPEAKER_00]: Thanks for being on code story. [SPEAKER_00]: Awesome. [SPEAKER_00]: Excited to be here and looking forward to explaining a lot more of what's happened behind the scenes when it comes to AI infrastructure and how that really emerges for all of the agents that your audience is actively building and developing with. [SPEAKER_01]: Absolutely, it's such an interesting time where the industry is moving so fast and a lot of people are putting their hands to keyboard and using AI tools, and using generator tools and the models and all the things out there that are improving the lives, but behind the scenes, the hardware problem, the hardware optimization is real and a lot of people don't get to see that.
[SPEAKER_01]: So I'm really excited to dive into that. [SPEAKER_01]: Before we do, what I'd really like to do is have you tell me in the audience a little bit about you. [SPEAKER_00]: I lead product marketing and developer relations and some of, before that, I've been around Silicon Valley and a bunch of different startups from virtual reality to AI where I am today. [SPEAKER_00]: And it's super interesting diving in and having been with someone over for the last couple years to really dive into the hardware and infrastructure that is driving that this AI revolution.
[SPEAKER_01]: curious about if you can tell me a little bit about Sam and Nova and how you and the team are solving these types of problems. [SPEAKER_00]: So I'm going to have been around since 2017 so it's not new and it has produced many chips in that time as a hard work company. [SPEAKER_00]: It was co-founded by two Stanford professors with partnering with a pioneer from the Sun and Oracle days, the name is Rodrigo Lyon, and together they've really come up with this innovative idea
[SPEAKER_00]: to create this chip called a reconfigurable data flow unit, RDU. [SPEAKER_00]: And it fundamentally works very differently from GPUs in the way that it maps the hardware in a way that is much more spatially oriented to how AI operations work. [SPEAKER_00]: And it's been taking a lot of the the research that's been happening and building that into the silicon layer in a way that's reconfigurable and usable across many different AI models, but also much more tuned to the data flow graphs that AI models are created against so that you can get much more energy efficient operations as well as also delivering tokens much more faster.
[SPEAKER_00]: which will be incredibly important to a lot of the agentic AI applications that everyone is building today. [SPEAKER_01]: Awesome. [SPEAKER_01]: So tell me about when you joined the company. [SPEAKER_01]: What brought you to San Mova and what problem or what thing really drew you to the mission? [SPEAKER_00]: When I joined two years ago, the company was at a very different stage and it's journey. [SPEAKER_00]: But one thing that I did see that it has been true and how we have really reshaped the way we go to market is that fast tokens.
[SPEAKER_00]: aren't incredibly important. [SPEAKER_00]: And in the AI applications, I was building myself as a technical product marketing and engineer by trade is that fast tokens are always going to be important especially as you start to chain a lot of these, the LM requests together. [SPEAKER_00]: And I saw some of the early demos that Tom and Ova had demonstrated at the time it was on its fourth generation [SPEAKER_00]: fifth generation chip that the shipping to customers later this year. [SPEAKER_00]: And I knew that was really going to be absolutely critical for how AI gets deployed in production and it's going to be incredibly important.
[SPEAKER_00]: And lo and behold, that has started to become even more apparent in whether you look at anthropic and the need for fast tokens through cloud opus 4.6 as well as later versions like 5. [SPEAKER_00]: definitely true with open AI in their fast mode and it's been interesting to see also the leading inference providers also get really hungry for fast tokens on some of these open source models like himmy or GLM and that that thesis that I had when I joined has been growing and revalidating itself which is that [SPEAKER_00]: As AI gets deployed in more and more in production, you need faster and faster tokens.
[SPEAKER_00]: And how do you get that? [SPEAKER_00]: You get that through really optimized hardware like the the Somba Nova R to use. [SPEAKER_01]: Awesome. [SPEAKER_01]: I appreciate that overview and a bit into Somba Nova. [SPEAKER_01]: Let's dig into our topics for today. [SPEAKER_01]: The first area of topic is shift to autonomy and chat responses, right? [SPEAKER_01]: When we shift from a user generating a single response, [SPEAKER_01]: to an autonomous agent, executing dozens of background tool calls, loop checks, and file rewrites, all the things that it can do automatically.
[SPEAKER_01]: How does the underlying inference profile change? [SPEAKER_01]: And what metrics break first? [SPEAKER_00]: 100%. [SPEAKER_00]: It's really interesting to see how just in the short spent of time, like two years, we've gone from [SPEAKER_00]: these chatbot single-shot responses to agents when you go to cloud code, cloud code work, opening a code access, etc. [SPEAKER_00]: All of these different tools are now chaining together LLM requests to be able to solve a end to end task. [SPEAKER_00]: and really go deep and create even more detail on top of that, which is not just one agent, but subagents that are breaking down tasks and are super specialized into a specific domain.
[SPEAKER_00]: And in that, what has occurred is that the amount of inference that you need has grown exponentially. [SPEAKER_00]: And the challenge that the industry as a whole is trying to figure out when it comes to deploying
[SPEAKER_00]: But how do you balance the completeness, especially when you're running really large models, like a Opus 5 or a GP5.6-hole, running that efficiently on hardware when these are really massive, 2 trillion, 3 trillion, 5 trillion, and the number of parameters are continuing to grow on these models, which translates to much more memory usage. [SPEAKER_00]: while also ensuring that these models run really fast so that your agents which are creating a bunch of different LLM requests can reduce the time at each and every step with faster and faster inference to reduce the overall time that you get an answer.
[SPEAKER_00]: And this becomes incredibly important in a bunch of different use cases for whether that's with coding, or even a lot of the co-work use cases that we're seeing emerge as simple as PowerPoint creation, for example. [SPEAKER_00]: That's still an agent that's behind the scenes creating many different requests. [SPEAKER_00]: If you're familiar and have been using these tools, then you know that these agents can take minutes and oftentimes hours, even days, to produce results. [SPEAKER_00]: And so being able to figure out how we can take each of these individual building blocks of agents and run them significantly faster, [SPEAKER_00]: is really that next hurdle that the market in industry is trying to solve to optimize and get these agents into much shorter time to ask completion.
[SPEAKER_00]: And then as a result, creating a lot more usability and productivity that can be emerged by running these agents faster. [SPEAKER_01]: Excellent, so I didn't hear running the agents faster and getting through these tasks faster. [SPEAKER_01]: I start to come to the idea of budgeting, tokens, and things like that, and at the beginning, token per second throughput was a nice to have metric. [SPEAKER_01]: For human readability, but for multi-age workflows that are all running. [SPEAKER_01]: parallel and you're talking about speeding up the task low latency is critical to prevent the system timeouts.
[SPEAKER_01]: So how are developers designing prompt structures and context windows and all the things that go into building something like a request or an agent to prevent compounding latency during multi agent orchestration? [SPEAKER_00]: Yeah, so it's really interesting to where, again, that the industry changes so fast. [SPEAKER_00]: I think in even a year or a year and a half ago, the way developers would do that is by creating, you'd use a framework like a crew AI example. [SPEAKER_00]: And you manually go in and you'd say, I want an agent that's planning and I want a coding agent and I want a QA agent and a CSED agent, at manually going and craft all of my prompts and structures.
[SPEAKER_00]: What has really happened, what I would say just earlier this year with the introduction of Office 4.6, is and definitely much, I can just been getting better and better.
[SPEAKER_00]: And as a result, developers actually can get to the point where they can keep a very high level thoughts and contacts that they provide to the agent on what they want the end task to be. [SPEAKER_00]: and the agent itself will actually go out and write all of the structure and some of the agents. [SPEAKER_00]: That's very true, even in my day to day, when I use OpenClaw or Hermes, or even CloudCode, that the agents are smart enough to break down the problem in such a way that you can bifurcate it into a bunch of different sub-tests.
[SPEAKER_00]: And that manages and keeps each of these agents relatively isolated where their contacts windows are can be manageable and they can still interoperate with all these different agents. [SPEAKER_00]: And the beauty of also that architecture is that different agents can use different models and you can reduce your overall cost and improve your overall efficiency in doing so. [SPEAKER_00]: For example, the very common architect that we see is planning is the most complicated bit you want almost always a frontier model to be doing that whether that's fable, opus, gpd5.6.
[SPEAKER_00]: But these subagents, especially in code execution, there are so many great open source alternatives there and they need to generate thousands and thousands of lines of code. [SPEAKER_00]: And you can take a model like a GLM or a kimi or a mini max and use that for the execution and even our teams today use that at someone over and dramatically reduce the time that it takes for the agent to run and dramatically reduce the overall cost, which is I think that the two key variables that any developers really trying to optimize when bringing these into production.
[SPEAKER_01]: Now, I think that is interesting. [SPEAKER_01]: It's a super fascinating area to kind of dig into and moving forward. [SPEAKER_01]: We think about like optimal hardware mix inside the rack. [SPEAKER_01]: A hyper-scalors historically standardize on monolithic hardware, but the nowadays Neo Clouds are increasingly mixing high-memory GPUs, specialized inference, A6, and custom interconnects. [SPEAKER_01]: How do you just side with that optimal hardware mix is inside the rack? [SPEAKER_01]: when you're customer demand fluctuates between the massive long context reasoning models versus rapid edge like the code.
[SPEAKER_00]: Yeah, it builds on on on on this agenda can first structure, right? [SPEAKER_00]: So each and other ones that are creating this demand, that then needs to trickle down into how you plan your data center. [SPEAKER_00]: And it's been largely general purpose today with GPUs, but the unfortunate reality is that this is because of their architecture being much more well-suited, graphics workload, and that's what they were optimized for and poured it over to AI. [SPEAKER_00]: They have structural memory bandwidth problems when it comes to processing AI workloads.
[SPEAKER_00]: And that just leaves a big gap for these premium fast and French workloads that developers and anyone who's using agents are craving. [SPEAKER_00]: And in that broader data center ecosystem, if you want to serve all of these different requests and people are already paying and have such a big desire to have these rich agents run faster because they can get way more productivity out of it. [SPEAKER_00]: Then you have to think about, okay, I might have some use cases where I can have slow tokens, and I can use my GPUs that exists today.
[SPEAKER_00]: I obviously have AI training workloads that I need to keep running on GPUs. [SPEAKER_00]: But then for this emerging class of agents that need fast inference, you need to start bringing that into the data center. [SPEAKER_00]: And if you think it becomes also even interest day without going to a bunch of detail, they're happy to, we where you can use different architectures and infrastructure together to improve that overall utilization and what's called disaggregated inference. [SPEAKER_00]: and using GPUs on the pre-file side using custom ASX or RDU's in our case in the the decode side, you can create that best of both worlds scenario where you're maximizing the utilization of cross-fear overall stack.
[SPEAKER_00]: You are delivering these faster tokens that are helping these agents from faster and then the end result is of course you're getting much more productivity out of anyone that's using the infrastructure. [SPEAKER_00]: And that's really the holy grail, if you will, that we're really trying to move towards, where the full stack kind of gets optimized from the infrastructure to the use cases and the outcomes that everyone was using AI is fully craving. [SPEAKER_01]: Interesting. [SPEAKER_01]: Yeah, it's interesting, and the word craving makes a lot of sense too, and craving that optimal mix, but sticking in the area of Neocloud data center, and how they're architecting, maybe it's not the right word, organizing the layouts, engineering, cooling, and power distribution all the things, the high-end inference accelerator, so they draw massive power, how are the
[SPEAKER_01]: this. [SPEAKER_01]: Again, the reengineering look of cooling, rack layouts, parish, fusion, all the things that they've got to optimize, specifically to maximize inference density, rather than training throughput. [SPEAKER_00]: I think there's a lot of challenges that are happening at the data centers around the world. [SPEAKER_00]: I think that there are some advantages in liquid cooling that the biggest challenge is today 80% of data centers approximately are air cooled across the world.
[SPEAKER_00]: 20% of them are liquid cooled. [SPEAKER_00]: And the challenge that we're seeing when it comes to inference and AI deployment is you need a ton of GPUs or orchestrated together in a scale-up network to be able to deliver the performance profiles that you might want to have at inference. [SPEAKER_00]: And that has to sit within a liquid-cooled data center. [SPEAKER_00]: Except for the problem that we don't have a ton of liquid-cooled data
[SPEAKER_00]: are currently being built out or with the hyperscalers, which leaves this big opportunity to say, how can we use our existing infrastructure, which is 80% of the data centers out there in the world today, which is not that complicated because it's out of the air cooling. [SPEAKER_00]: and use that to get the best performance for inference. [SPEAKER_00]: And because especially given that inference is the predominant workload for AI, and one other thing for someone over that, that's incredibly important is because of the way the data flow architecture works.
[SPEAKER_00]: We're able to significantly reduce the energy that that you take to run AI and approach workloads. [SPEAKER_00]: And the reason at the simplest level is because memory movement is the most energy expensive thing that you can do on any, any chip. [SPEAKER_00]: And if there's a ton of memory movement that's needed with a lot of these AI workloads, and if you don't have a data flow where operations are moving seamlessly from one to the other without going to HBM, you, in the GPU paradigm where you don't have that, [SPEAKER_00]: You end up using a ton of energy and it becomes incredibly inefficient with with our RAU paradigm That that's exactly where we've optimized for and that allows us then to create these racks that fit into data centers That have that that can be air cool without the need for liquid [SPEAKER_00]: And as a result, you can take advantage of that 80% of the data centers that are out there today and start to put deploying really high performance inference in them, which I think is just a massive market opportunity that I think a lot of new clouds are actively exploring because everyone is compute constrained, a lot of enterprises are looking at it at that as well.
[SPEAKER_00]: And I think that was one of the things we'll take a few more [SPEAKER_00]: And they recently signed with us like that. [SPEAKER_00]: That was a key attractors. [SPEAKER_00]: That is a fact that we can actually have our racks sit within these air cool data centers and make it significantly better for them to run their infrastructure uploads. [SPEAKER_01]: interesting. [SPEAKER_01]: This is all really fascinating engineering problems to solve and really interesting option optimization things.
[SPEAKER_01]: So I want to dig into the coupling pre-fill and decode and really the biggest real-world friction points that are present when deploying this in production. [SPEAKER_01]: Disaggregated inference splits compute heavy pre-fill operation. [SPEAKER_01]: From memory bandwidth,
[SPEAKER_01]: So, what are those biggest real-world friction points when deploying this in production? [SPEAKER_01]: And I think the area is interesting, especially around the Katy Cash transfer overhead and internode networking. [SPEAKER_01]: Lots of words there. [SPEAKER_00]: Yeah, and we hinted at it earlier when we were talking about the data centers. [SPEAKER_00]: And I think what's really emerging, especially amongst the high
[SPEAKER_00]: is different shifts at the end of the day are specialized and will get higher utilization for different parts of the inference workload. [SPEAKER_00]: That's really the real bottleneck. [SPEAKER_00]: So maybe to break this down, right? [SPEAKER_00]: So pre-fill is when you've typed your input into chatGBT, and it needs to convert your text into all of the tensors and vectors and matrices. [SPEAKER_00]: The mathematical representation, if you will, which is what we call the KB cache, and that creates the context for it to then move to the next phase, which is decode, which is where you're generating token by token one at a time.
[SPEAKER_00]: and they're very fundamentally different operations. [SPEAKER_00]: Pre-fill, as you can imagine, these, the input context links for a lot of these agents is in the hundreds of thousands approaching a million on some models. [SPEAKER_00]: And that's a huge amount of context that needs to be computed as fast as you can. [SPEAKER_00]: And so the workload is really designed for how much compute and I throw at this problem to generate that KV cache. [SPEAKER_00]: Then you go to decode. [SPEAKER_00]: And decode is, as I would talked about before, is memory bound.
[SPEAKER_00]: It is how fast can you move this giant KV cache of all of that context and use that to generate token after token while I'm continually adding onto it for each and every token that I generate. [SPEAKER_00]: And it is a function of these really large models, which have really big grammar counts, paired with really large kvcaches that then are creating this big bottleneck when it comes to running large models as fast as you can. [SPEAKER_00]: But what that tells you is that, okay, I need to think about these problems very differently, and I need to have different hardware that runs in each of those workloads.
[SPEAKER_00]: and the third part is I need to have really good networking that can make sure that the latency between transferring from chip to chip is as low as possible. [SPEAKER_00]: It's possible then can I go ahead and do anything to [SPEAKER_00]: overlap the compute with the memory latency and the network transferring to reduce the perceived latency. [SPEAKER_00]: And so you have really these three buckets that are all working together in the data center. [SPEAKER_00]: So on on pre-fill what we see today is that's largely GPUs.
[SPEAKER_00]: On decode, we're seeing this growing interest around different solutions, like some of those are to use. [SPEAKER_00]: And then the networking that ties that all together is its whole set of wraps that create this scale up and scale out network that ties this all together and moves the bits across all of these different ships as fast as you possibly can. [SPEAKER_00]: and doing all of those things well is incredibly difficult, but when done well, it allows you to maximize the overall utilization, and then improve at the end of the day from a new close perspective, the ROI that they're actually getting on this infrastructure investment.
[SPEAKER_01]: It's really interesting, and you can tell by the points you're making there that gloves really dig into this, do the hard work, right up front, and to these optimizations, they're going to see benefit. [SPEAKER_01]: It's moving to kind of a dynamic orchestration. [SPEAKER_01]: In a disaggregated setup, workloads spike or workloads spikes, he's me in long context coding props can saturate the pre-fill. [SPEAKER_01]: while leaving decode nodes under utilize our leading engineering teams building smart rounding layers and dynamic auto-stealing engines to balance compute the cross compute bound and memory bound hardware like how are they setting this up to where they can run the best where there are bouncing place and I think that's exactly the biggest challenge that these leading engineers are trying to solve.
[SPEAKER_00]: On one hand you want to maximize the ROI on the
[SPEAKER_00]: to rigid for a very specific workload that when workloads change and even something as simple as you get a bunch of agent requests during the day and then maybe it falls out overnight. [SPEAKER_00]: You're not able to scale up and scale down your hardware needs as needed or maybe you have a bunch of kind of agents that are just ramping up but they're all really small context length and they haven't really
[SPEAKER_00]: Neoclouds and internet providers have to balance and maximize that utilization of the hardware. [SPEAKER_00]: And so as a result, you can't over-engineer the underlying hardware infrastructure. [SPEAKER_00]: But you want to get it to the point where there is a good chip to chip ratios when it comes to balancing pre-fill and decode. [SPEAKER_00]: Ideally, in the range of 1 to 1 or 1 to 2 or 2 to 1. [SPEAKER_00]: because at that level of fungibility, then it's almost equivalent in terms of having pre-philt, pre-fill, and decode nodes fully utilized across a wide range of workloads.
[SPEAKER_00]: What we've seen in some other scenarios is where let's say you're using an SRAM only solution. [SPEAKER_00]: The number of decode nodes that you need balloons because you don't have enough memory with just pure SRAM. [SPEAKER_00]: And as a result, you're going to have way too many nodes of SRAM and not and compared to the number of pre-filled nodes that you have. [SPEAKER_00]: And as workloads change, the balancing act that you have to do and it doesn't really play out. [SPEAKER_00]: And you end up in cases where you have pre-fill is generating way too many tokens and decode doesn't have enough.
[SPEAKER_00]: and you're over-supplyted on decode. [SPEAKER_00]: And that's exactly the problem that engineers are exactly trying to balance, which is really a function of how much throughput can I get out of my chips versus the SLO's that I'm getting out of my hardware in terms of the speed that tokens are coming up per user. [SPEAKER_00]: which is a very tricky trade-off, but as one that at Summonova were very cognizant of, to make sure that the pre-fill and decode can stay in balance across a wide range of workloads and make sure that these disaggregated setups are then able to be mature reliably used in production into the future.
[SPEAKER_00]: And I think that's just incredibly important because hardware is such a big investment up front and needs to pay itself out over any years for it to make sense. [SPEAKER_00]: And for that that happened, you need to have infrastructure that's able to be flexible and fungible over that lifespan. [SPEAKER_01]: No doubt it is, it's a heavy investment up front and it's a longer payback period. [SPEAKER_01]: And I like what you said that you can't over-engineer it, but you have to balance that.
[SPEAKER_01]: I think in doing so too, it could get to our last point around the economics, right? [SPEAKER_01]: Enterprise adoption is oscillating between proprietary API driven models and self-hosted open weights. [SPEAKER_01]: And everybody has the tipping point that they're looking for or that they need to be aware of where it's economically imperative to solve some of these problems or you know, go between these two, go from one model to the other. [SPEAKER_01]: At what scale does it become economically imperative for a company to transition off closed APIs?
[SPEAKER_01]: on to self-hosted open infrastructure. [SPEAKER_01]: And scale is really measured in inference volumes, latency, SLAs, data privacy, you could strange things like that. [SPEAKER_00]: If there's one takeaway from this conversation, is you can tell how complicated it is for. [SPEAKER_00]: setting up a really efficient infrastructure, and there's a ton of capex involved. [SPEAKER_00]: That's one of the reasons why all of the Neo Clouds are doing so well, and infrastructure are doing so well is because it is incredibly complicated, right?
[SPEAKER_00]: And from an enterprise perspective, it's not trivial, let alone the cost. [SPEAKER_00]: to also have the talent that's also there to set up this infrastructure as well. [SPEAKER_00]: Like this is an incredibly, incredibly niche set of skills that a lot of the neoclouds and inference providers have, have the, have curated over over many years. [SPEAKER_00]: And so I say all of that in the context of, [SPEAKER_00]: on-prem deployments are very challenging. [SPEAKER_00]: That's not to say that you can't work with a Neocloud or an inference provider.
[SPEAKER_00]: That's done all of this like we're to maximize and they've mapped this out also to all of the profiles they expect to see from enterprise and run those on those Neocloud. [SPEAKER_00]: And that's then what's deriving, okay, it's really more a choice of less, do I host this on prem and then maybe more a question of, do I go to the togethers or fireworks or based tens of the world versus anthropic and an open AI? [SPEAKER_00]: The vast majority of folks will start in that space and quite frankly, and then just tying this all back together to where we started is [SPEAKER_00]: that really, when you look at deploying these agents, you probably do start in the cloud and opening eye space of the world, and you use it to create all of this agent agent infrastructure, which is all of those prompts and frameworks that we talked about.
[SPEAKER_00]: And then you can slowly start peeling it back from the closed model into, okay, let me test this sub agent on an open model. [SPEAKER_00]: See how it performs.
[SPEAKER_00]: But that's the level of testing that
[SPEAKER_00]: every developer and every engineer goes to and it's really in that framework that's how enterprises will start to make that decision and it feels some of that back off and then the neoclows and inference providers will behind the scenes do all of that optimization to make sure that you get the SLOs that you need in terms of speaking performance across a wide range of heterogeneous hardware that's really happening behind the scenes. [SPEAKER_01]: Yeah, and I mixed total sense. [SPEAKER_01]: The song that I really appreciate you walking me through this.
[SPEAKER_01]: This is an area that is not an area that we talk about often on this show. [SPEAKER_01]: And I can tell that where we're going as an industry, Neo Clouds are interesting, super important. [SPEAKER_01]: And they're doing well. [SPEAKER_01]: They're seeing single huge benefits and huge dividends paid off of solving the real hard crops, right? [SPEAKER_01]: And architecting their data centers, the racks and their setups. [SPEAKER_01]: And to really increase the inference and be able to support this AI through.
[SPEAKER_01]: And the best engineering teams are trying to solve these problems with dynamic orchestration amongst these bounded systems. [SPEAKER_01]: But as you said, the big takeaway setting up these neoclides is incredibly complicated. [SPEAKER_01]: So at some point businesses have to be able to make the call of moving to self-hosted infrastructure over these closed API systems that. [SPEAKER_01]: They don't have any control of it. [SPEAKER_00]: There's a lot that's happening at the hardware layer.
[SPEAKER_00]: I'm truly exciting. [SPEAKER_00]: It's often hidden behind many layers, especially a current enterprises and software developers who are just so used to getting one API. [SPEAKER_00]: But when you start to build things back, it's really remarkable like all of the different components that are. [SPEAKER_00]: being built out to make something as simple as as you talking to an agent happen, and it's going to continue to evolve and get complicated over the next many years with so many people working across the stack.
[SPEAKER_00]: But the end goal of all of this is to make these AI agents that everyone was listening. [SPEAKER_00]: It's using perform really well and really efficiently, and that's going to continue to evolve over the next several years, which is going to be really exciting to watch. [SPEAKER_01]: Absolutely. [SPEAKER_01]: We look forward to follow it along in that evolution. [SPEAKER_01]: It's been exciting to watch the industry. [SPEAKER_01]: Of all that takes shape. [SPEAKER_01]: It's all some of these new problems that pop up as we start to use and make demands of these tools in the industry today.
[SPEAKER_01]: So again, thanks for being on the show today. [SPEAKER_00]: Yeah, my pleasure.
[SPEAKER_01]: AI is changing the game for how we do our business, build applications, and many other things. [SPEAKER_01]: But behind the scenes hardware setups, data centers, etc. [SPEAKER_01]: Need to be optimized to support a high volume of throughput of these types of requests. [SPEAKER_01]: Not only does sport what's happening now, but to be set up for success, as AI solidifies even more in our day-to-day lives. [SPEAKER_01]: If you'd like to learn more about San Benova, please check out San Benova.ai.
[SPEAKER_01]: And thanks again for listening.
Latest Season of the Podcast is Sponsored By


 Apple Podcasts
 Spotify
 Pocket Casts
 Castbox
 YouTube
 Player FM
 Overcast
 Castro
 Goodpods
 Moon FM
 Podbean
 Podcast Addict
 Podcast Republic